Skip to content

For companies

The right model for every call.

One layer over models from several vendors. Top models only where they change the answer, small fast ones everywhere else — and every call on a receipt.

Gateway coded and tested · switch-on in build

hu runs on the same engine.

Illustration

The bill grows with every new agent.

Most calls don’t need the most expensive model, and most prompts carry far more context than the answer needs. Both are fixable in one layer.

The right model for every step.

A router splits each job and sends every step to the cheapest model that clears the quality bar — a top model only where it changes the answer.

Router built · per-turn routing in build

Only the context that matters.

Memory brings back a few precise facts instead of whole histories, so prompts stay small as knowledge grows.

Built in our engine

Every call on a receipt.

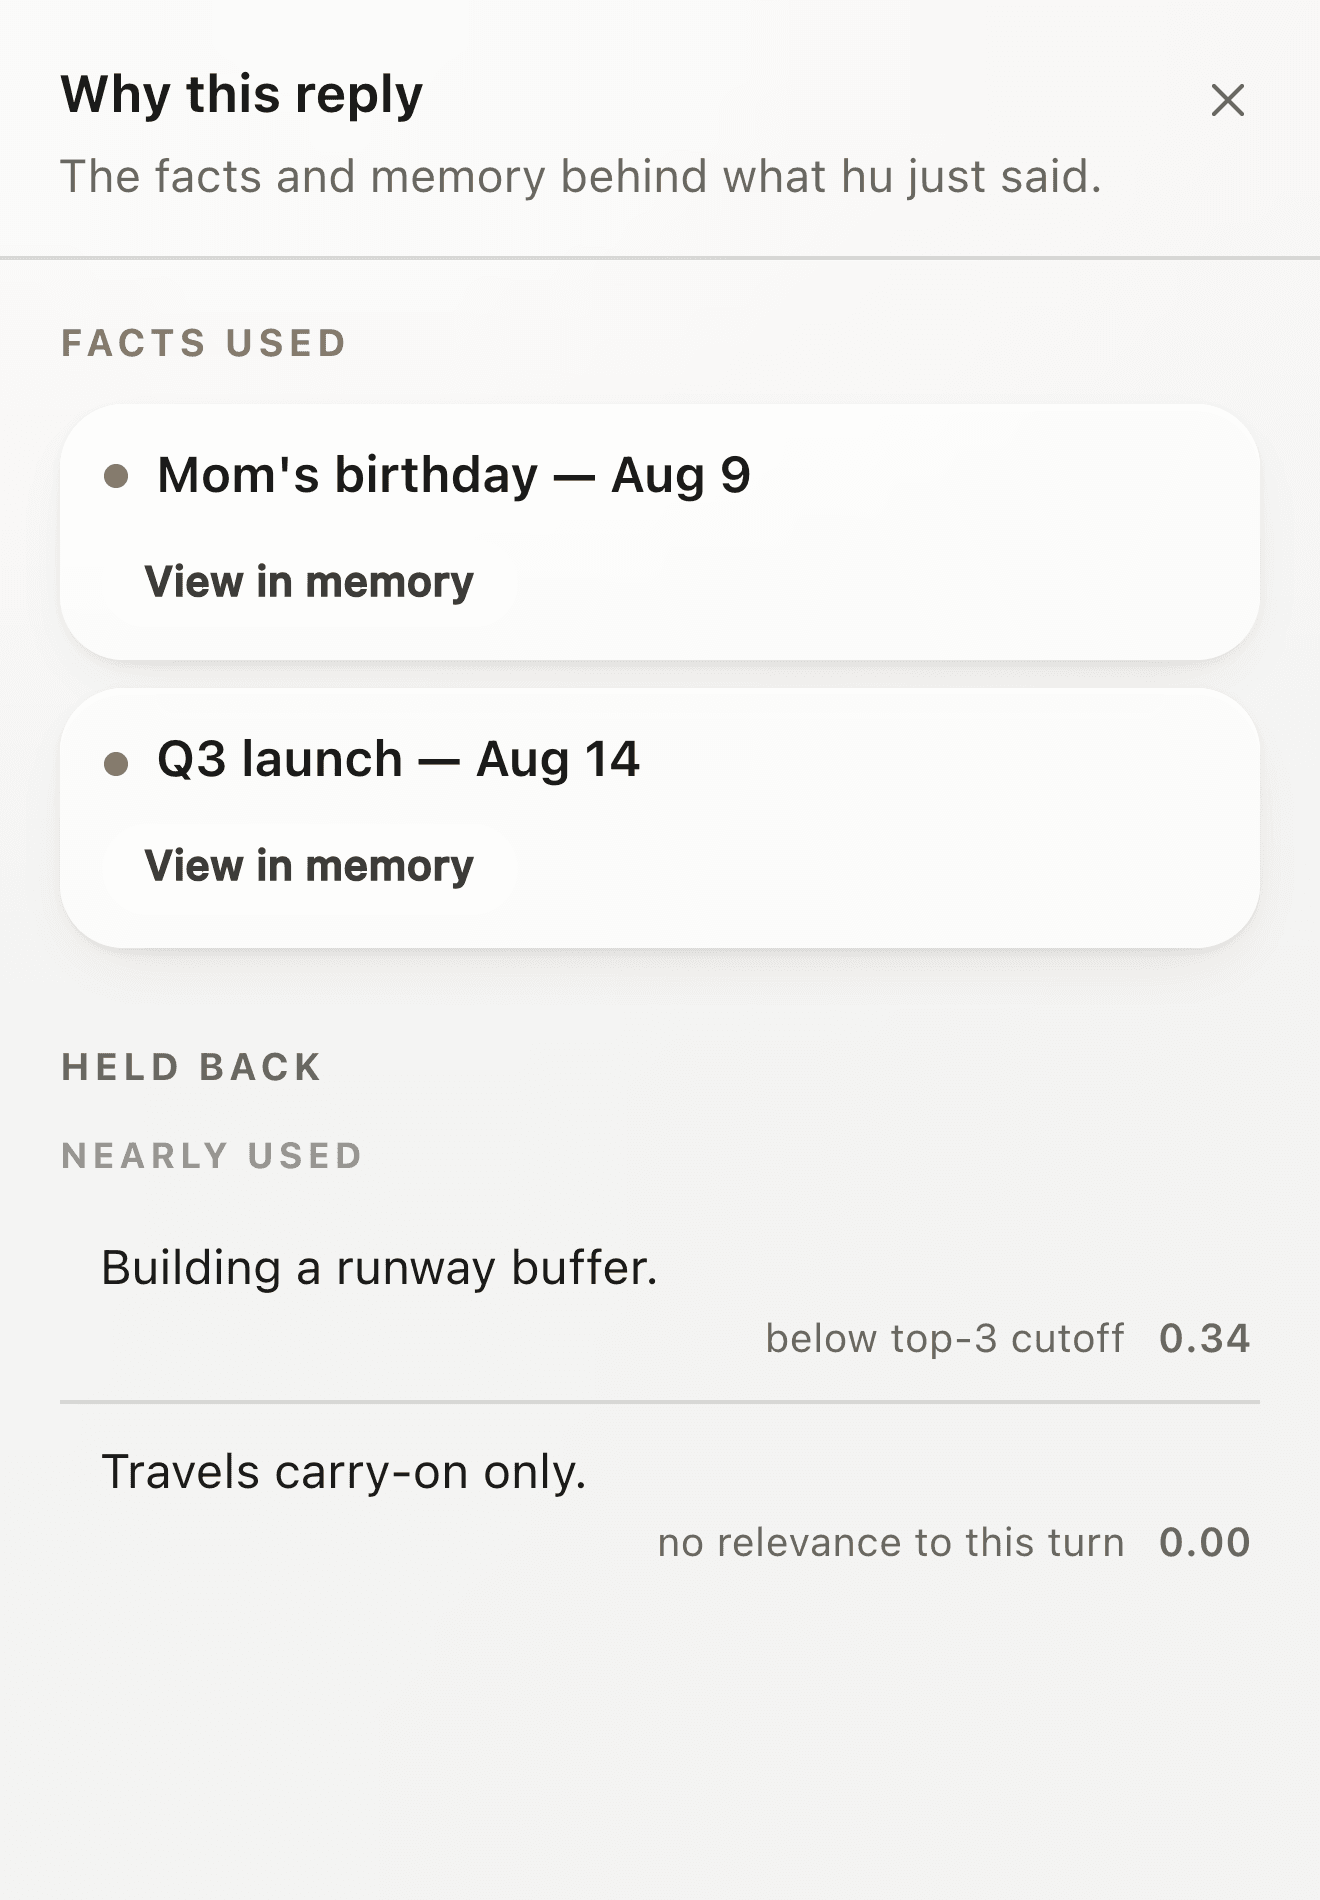
Each reply records the tokens, facts and sources it used, so cost and quality are visible call by call.

Built in our engine and the app

One layer

One job in. The right model for each step.

hu’s router splits the work: a top model where quality changes the answer, small, fast models for everything else — with budgets, ordered fallbacks and a receipt for every call.

In build · automatic routing
  1. One job comes in.
  2. hu splits it into steps.
  3. A top model only where it changes the answer.
  4. Small, fast models for everything else — and memory needs no model call at all.
  5. Every call lands on a receipt.

One job · four stepsReceipt

Reply to a customer about a late delivery

  • Read the thread — small · fast model
  • Recall the account — memory — no model call
  • Draft the reply — top model
  • Check the draft — small · fast, another vendor

Logged · every call on the receipt

Illustration · sample job

How we cut cost without cutting quality

Orchestration + a memory graph: several models cross-check each other while the graph keeps the context lean. Same quality bar — a fraction of the spend.

−61%

lower cost per 1,000 tasks

2.7×

cheaper per task

100%

auditable actions

99%

verified, honest output

Cumulative AI cost — 30 days, 100 seats

same workload · lower is better

Same quality, a third of the cost

task success · cost index

Tokens used on a long task

relative · lower is better

Cost per 1,000 long tasks

all-in token spend · lower is better

Memory grows. The prompt doesn’t.

A few precise facts instead of the whole history — so a year in, a reply carries about as much context as it did on day one.
Illustrative: the shape of the curve, with no values. The chip is a receipt from the app, on sample data.

Controls your team can audit.

Does the workChecks it — another vendor
The judge is never the doer
Where hu checks work — memory updates, emotional reads, evaluations — the checking model comes from a different vendor than the one that did the work. Enforced in code.Built in our engine
Asks before it acts
Agents work inside permission tiers. Anything that sends, books or pays waits for a person, and grants can be revoked.Built in our engine
Every action logged
An append-only record of every action and every judgment.Built in our engine
Private stays private
Private facts never surface — not even through a link.Built
Recall without a model call
Memory retrieval itself needs no LLM call, so the cheapest step stays cheap.Built in our engine
No lock-in
One gateway across vendors, with budgets, ordered fallbacks and receipts by user, seat, model and day — change models without changing your stack.Coded and tested · switch-on in build
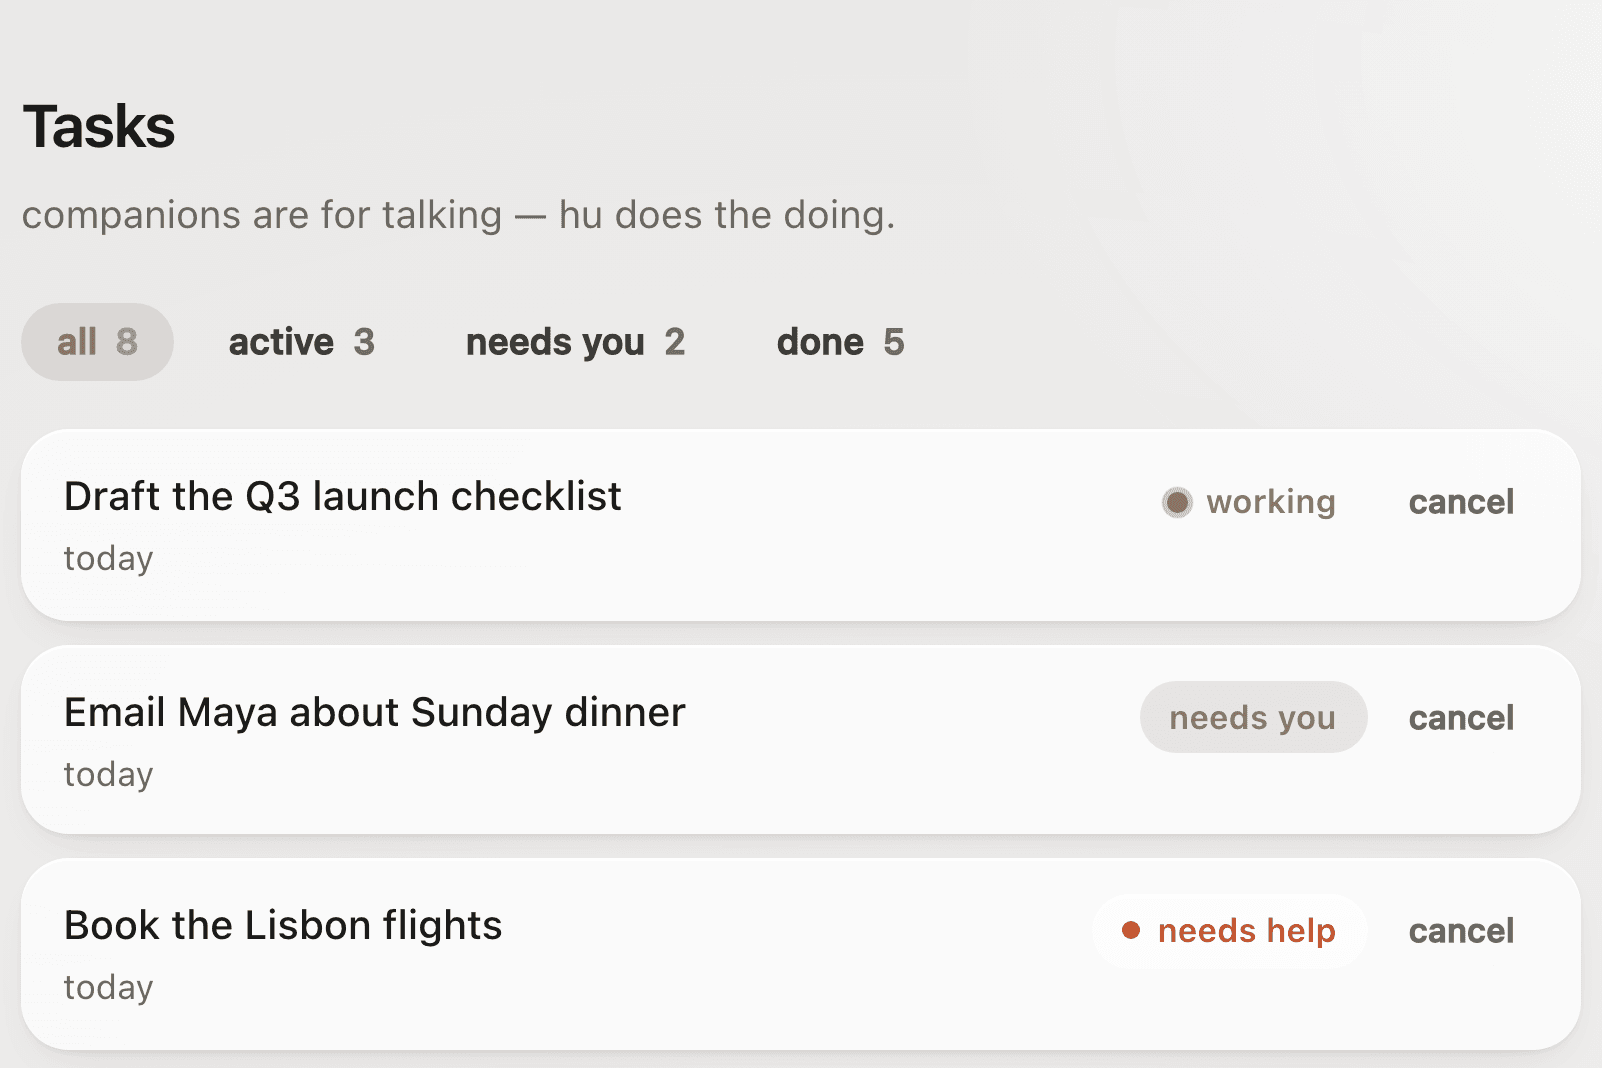
hu tasks waiting for a yes: “Email Maya about Sunday dinner” needs you before anything is sent.hu tasks waiting for a yes: “Email Maya about Sunday dinner” needs you before anything is sent.Product UI · sample data
Nothing is sent without your yes
The “Why this reply” panel: the facts hu used (Mom’s birthday — Aug 9, Q3 launch — Aug 14) and the facts it held back, with the reason for each.The “Why this reply” panel: the facts hu used (Mom’s birthday — Aug 9, Q3 launch — Aug 14) and the facts it held back, with the reason for each.Product UI · sample data

We’re looking for a few design partners.

If your AI bill grows with every new agent, tell us about the workload. Bring a real one — we’ll tune routing and memory on it with you.

Next · B2B design partners

Good fit

  • You run several AI features or agents in production.
  • You can name a quality bar for them.
  • You want to see cost and quality per call.
Become a design partner

See the engine at work.

hu, our personal AI, runs on the same layer. Open it in your browser.

Your own hu, ready in a minute.